
MiniMax H3 text-to-video workflow
MiniMax H3 turns a prompt into a video with its sound generated in the same pass: describe the scene, the motion and what is heard, and the clip comes back with audio. It is the most used video workflow on Graydient, with a large library of fine-tuned styles and motions that drop in as LoRAs. Open weights, hosted and ready to call; no setup.
Compatible / Available in Graydient-powered Apps
Sample renders
Made with the models this workflow runs. Prompts are credited on BunchaPrompts; the model opens on ModelTrends. Pick a thumbnail to see the render large with the prompt that made it.
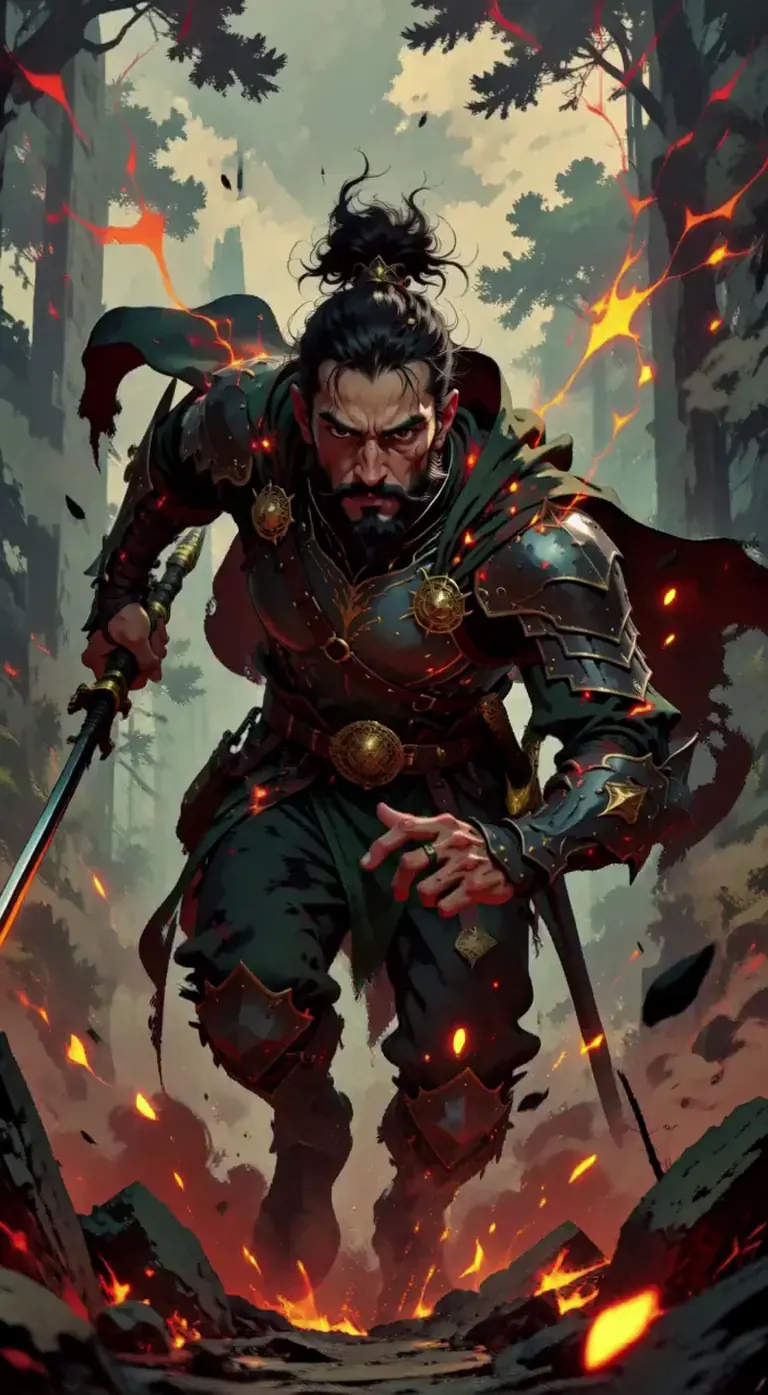


Prompt by Moonbear_AIArt on BunchaPrompts · Grandline - Legendary Stylized Illustration
a stylized illustration of a warrior lunging forward through smoke and sparks, cloak whipping in the wind, embers trailing behind, intense forward motion, dynamic perspective, cinematic lighting
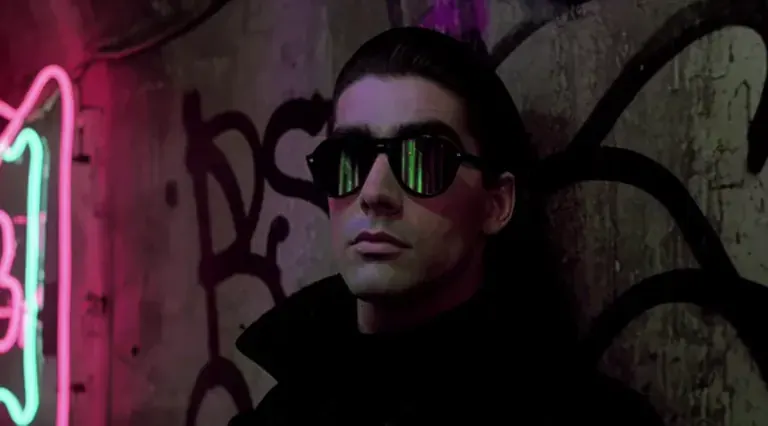
Prompt by FuenfFingerFaultier on BunchaPrompts · Dark Cinematic Video
Cinematic close-up shot of a 30 y.o. man with mirrored sunglasses and a long black coat, leaning to the wall of a dirty neon-lit tunnel with graffiti on the wall. Looking very cool and handsome, dark hair slicked back. He looks to the viewer and takes off his sunglasses, revealing large, ridiculous googly eyes underneath. Techno dance music, flickering lights. 1980s movie, high resolution. Photorealism, 8K, soft focus, depth of field.
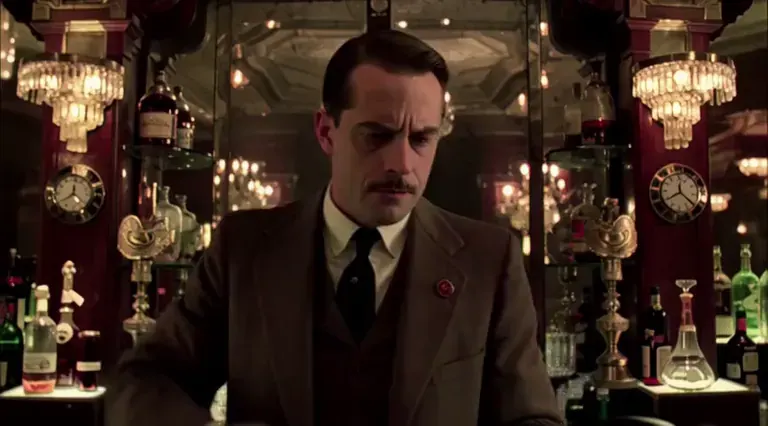
Prompt by FuenfFingerFaultier on BunchaPrompts · Dark Cinematic Video
Cinematic medium shot of a bar keeper in a very posh, 1950s upscale bar. He picks up an old-fashioned telephone and puts it to his ear. A distorted voice on the telephone says "Is your refrigerator running?". The bar keeper answers "yes". The voice on the phone says "Then you better catch it" and bursts out laughing. The bar keeper hangs up the phone with a trembling hand. He looks into the camera angry, furrowing his brow and clenching his jaw, then cries out in anger. No music. 2020s movie, high resolution. photorealism, 8K, sharp focus
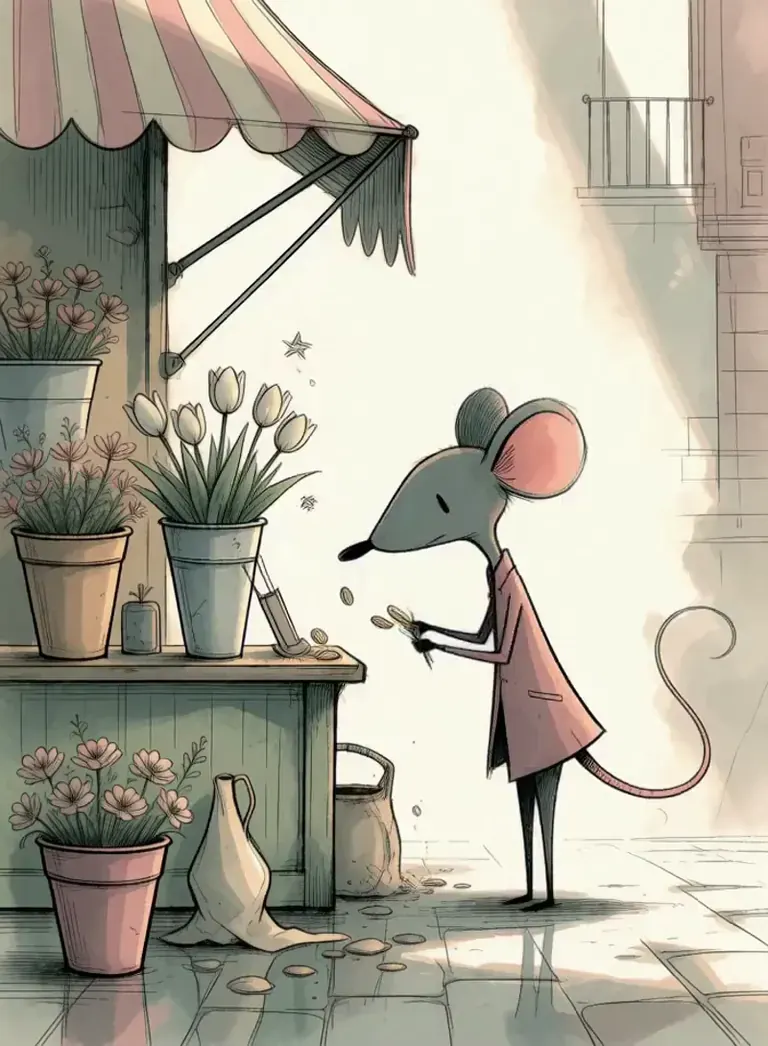
Prompt by liutyi2 on BunchaPrompts · Strange Reverie
StrangeDaal, pink coat mouse mouse buy a 3 flowers bouquet and walk with the bouquet down the street
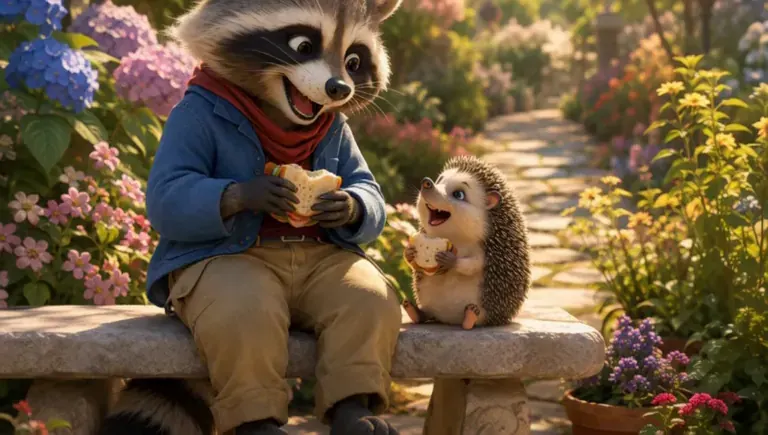
Prompt by Solricks on BunchaPrompts · 3D Animation Style
3dsrx, a raccoon wearing a blue denim jacket and a red scarf sits on a stone bench, holding a sandwich in his left hand and a small piece of bread in his right hand. The raccoon has a friendly expression and is looking at a hedgehog sitting on the same bench. The hedgehog is holding a piece of bread in its right hand and has a happy expression. The background features a garden with colorful flowers, including purple and pink blooms, and a stone path leading into the distance. A lamppost stands in the background, and the sun is shining brightly, casting a warm glow over the entire scene.
Prompt by ReltivlyObjectv on BunchaPrompts · Stylized PBR Animation [MiniMax H3 Ref2VA]
PBRSty1e, highly detailed cinematic video, complex crowd motion, rich environment. A bustling medieval marketplace at golden hour. Dozens of people move naturally through the frame — merchants calling out, children running, carts rolling over cobblestones. Colorful cloth canopies sway gently, hanging lanterns glow warmly, and dust floats in the low sunlight. The camera tracks slowly forward at eye level through the dense crowd, weaving between people, occasionally brushing past hanging fabrics. Strong depth, layered movement, realistic cloth and ambient life. Mood is lively, warm, and immersive.
Prompt by CitronLegacy on BunchaPrompts · BOTW Zelda Style [Minimax H3]
b0twC1tr0n, a pointed-ear young man with tousled blond-brown hair, wearing a dark business suit with a white shirt and black tie, he puts on cool sunglasses then crosses his arms confidently and smirks, and says "deal with it" the background is a dark starry void with faint streaks of light, high-contrast dramatic lighting, stylized cel-shaded rendering, moody surreal atmosphere, camera holds a medium close-up with small amplitude at slow speed
Prompt by CitronLegacy on BunchaPrompts · BOTW Zelda Style [Minimax H3]
b0twC1tr0n. A small armored figure stands at the center of a fiery starburst explosion on a grassy hillside, with two goblin-like enemies and a skeletal horned creature nearby amid smoke and floating embers. Scorched orange-tinged grass and scattered bones surround the blast, dynamic explosive action, intense combat lighting, vivid fantasy battle atmosphere.
 Prompts from BunchaPrompts. Workflows and models on ModelTrends.
Options
| Option | Maps to | Default |
|---|---|---|
(prompt) | CLIP Text Encode → text | — |
/guidance | KSampler → cfg | 4 |
/length | Empty MiniMax Latent → length (frames) | 125 |
/seed | KSampler → seed | random |
/size | Empty MiniMax Latent → width, height | 640 × 640 |
/steps | KSampler → steps | 20 |
Models used
 MiniMax H3 Video
Model imported by shortcode
/run:minimax-h3 from ModelTrends
See it on ModelTrends
For Developers (optional)
Example API snippet. You can build your own app with this workflow for personal use. Contact us for high availability servers when you're ready to deploy to the world. See the full rendering API documentation.
curl https://cloud.graydient.ai/api/v3/render/ \
  -X POST \
  -H "Content-Type: application/vnd.api+json" \
  -H "Accept: application/vnd.api+json" \
  -H "Authorization: Bearer $GRAYDIENT_TOKEN" \
  -d '{
    "prompt": "/workflow /run:minimax-h3 /size:640x640 /length:125 a parrot in a pirate hat dances on the deck of a ship at sunset while a sea shanty plays",
    "callback_url": "https://example.com/webhook/render"
  }'
This is how it works behind the scenes. This is already configured for you. The parameters in the table above plug into these slots, allowing you to change how it works and which models get loaded. You don't have to understand or modify this - it just works, already set up.
Read-only view. The highlighted pills are the options a call can set. Describe the sound as well as the picture; the fine-tunes change the style or the motion.
All the workflows: Powerful Workflows